
Llama-Guard-4-12B: Building Safer AI Applications with Text and Image Moderation
Learn how Llama-Guard-4-12B classifies text and image inputs, detects potential safety violations, and helps developers build AI moderation workflows.
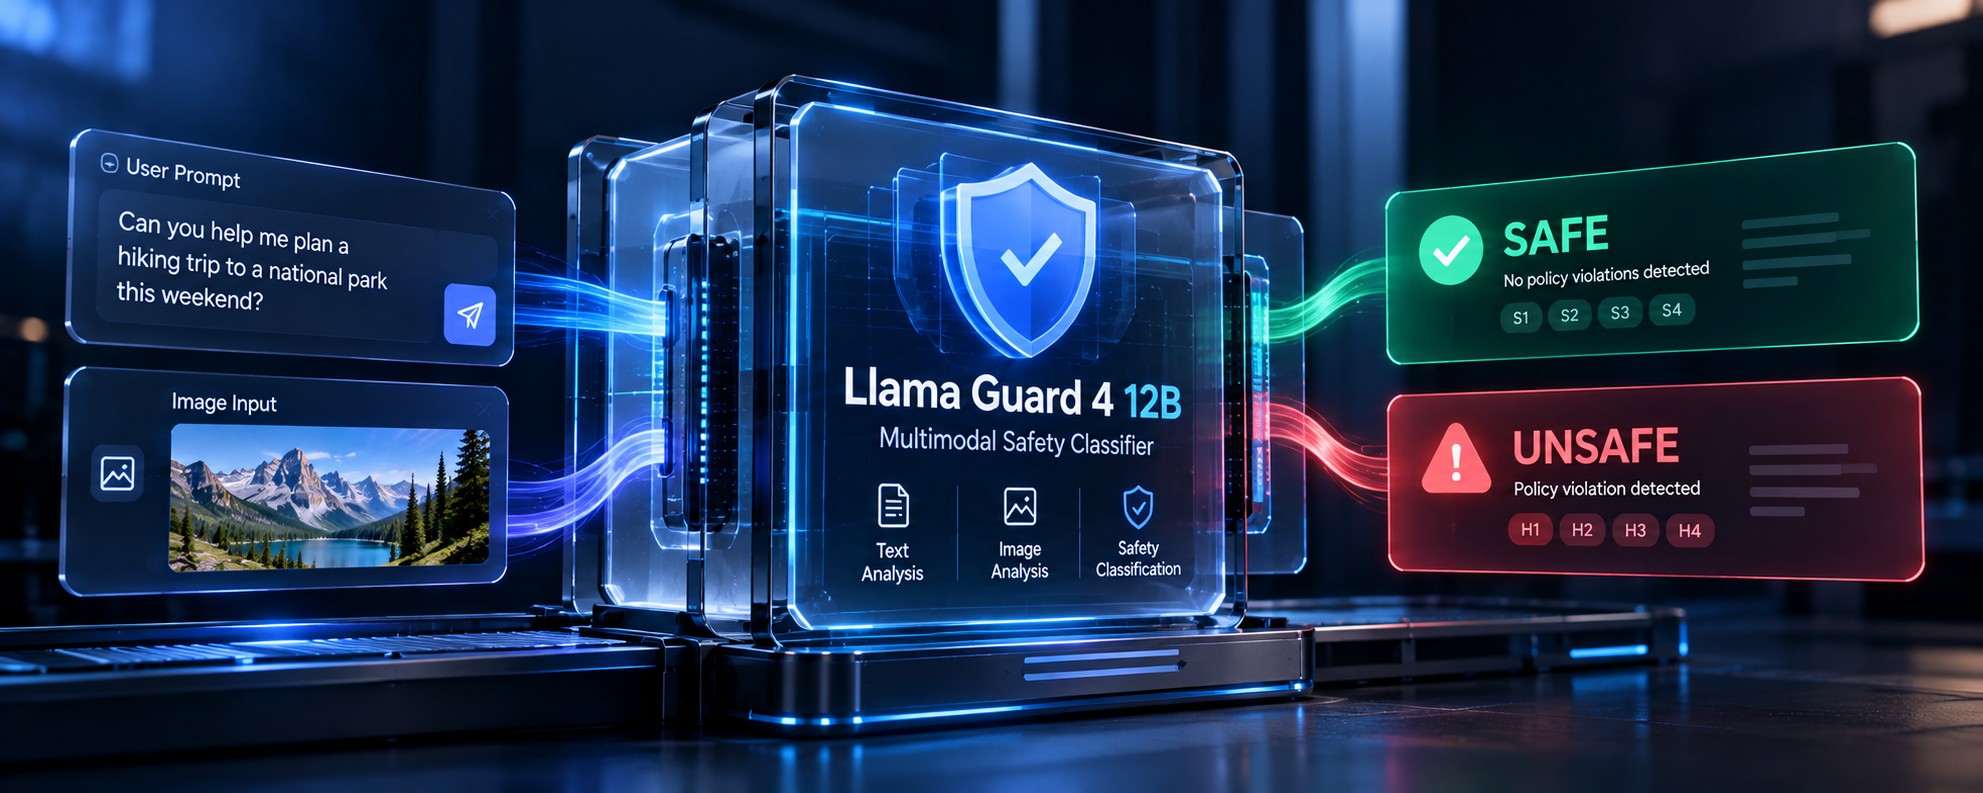
Building an AI application involves more than generating useful answers. Developers also need to consider what users submit, what an AI model produces, and how potentially harmful content is handled. As applications begin to process both text and images, checking these different inputs becomes an important part of the development process.
Llama-Guard-4-12B is Meta's multimodal safety classification model, designed to help developers identify content that may violate defined safety guidelines. It can evaluate text and image combinations and classify prompts or model responses as safe or unsafe. When content is classified as unsafe, it can also return the categories associated with the detected risk.
Instead of replacing a chatbot or generative model, Llama Guard works alongside other components in an AI application. It provides a safety-checking layer that developers can use before a request reaches a model, after a response is generated, or at both stages.
What Is Llama-Guard-4-12B?
Llama-Guard-4-12B is a 12-billion-parameter, dense, multimodal safety classifier developed by Meta. It is based on the Llama 4 Scout model and fine-tuned for safety classification rather than general-purpose conversation.
Its main job is to inspect content and determine whether it falls within the safety rules represented by its classification framework. The model can process text-only inputs as well as prompts containing text and multiple images. This makes it useful for applications where a simple text-only moderation check is not enough.
The model produces a structured text classification rather than a creative answer. A safe result is represented by safe. An unsafe result is represented by unsafe, followed by the relevant safety category codes.
Key Features of Llama-Guard-4-12B
1. Text Safety Classification
The model can evaluate text submitted by users or generated by another AI system. This allows developers to check potentially harmful requests before processing them or review generated answers before showing them to users.
For example, an AI support assistant could check incoming messages for policy violations, while a writing application could inspect generated content before displaying it. The application decides what action to take after receiving the classification.
2. Multimodal Text and Image Analysis
One of the model's defining capabilities is its ability to evaluate text together with images. An application can use it to check a message that includes a picture, or review a conversation containing multiple images.
This is especially relevant for image-sharing communities, visual question-answering applications, and AI assistants that accept image uploads. However, Llama Guard 4 is not intended to perform image-only classification: the image should be evaluated in the context of accompanying text. Meta also documents restrictions on evaluating images created using generative AI, so supported input conditions should be checked before deployment.
3. Safety Categories, Not Just a Binary Result
A simple safe-or-unsafe decision can tell an application whether content needs attention, but category information helps explain why it was flagged. Llama Guard 4 can return category codes alongside an unsafe classification.
These categories follow the MLCommons hazards taxonomy and cover different types of potentially harmful content, including certain criminal activities, violence, sexual content, child safety risks, privacy concerns, self-harm, and other defined hazards. The exact categories and their meanings should be taken from the model's official documentation.
4. Input and Output Moderation
Llama Guard 4 can be used at two points in an AI workflow. Input moderation checks a user's request before it is sent to a generative model. Output moderation checks the generated response before the application delivers it to the user.
Developers can use either approach or combine both. Checking inputs can stop certain unsafe requests early, while checking outputs provides another opportunity to catch problematic content that appears in a model's response.
5. Designed for Integration into AI Systems
Llama Guard 4 is intended to operate as part of a broader AI application rather than as a standalone replacement for all safety controls. It can be paired with generative language models, application-level rules, human review, and other security measures.
This separation makes it possible to update the application’s moderation workflow without treating the content-generation model and the safety classifier as the same component.
How Llama-Guard-4-12B Works
A typical integration follows a straightforward process. The application supplies content for evaluation, receives a classification, and applies its own rules to decide what happens next.
Step 1: Receive content
Collect the user's message and any supported image inputs.
Step 2: Run safety classification
Pass the content to Llama-Guard-4-12B using the required model prompt format or API interface.
Safe
Continue processing under the application's rules.
Unsafe
Block, review, restrict, or otherwise handle the content.
The classification is an input to the application's decision-making process, not a guarantee that content is harmless or harmful in every context. Developers should define how each result is handled and test the complete workflow against their own policies.
Common Use Cases
AI Chatbots and Virtual Assistants
Chatbot developers can check user prompts and generated replies for content that falls outside their application's safety rules. This is useful for customer support, education, productivity tools, and other conversational experiences.
Community Platforms and User-Generated Content
Platforms that accept messages, captions, or image-supported posts can use a safety classifier as part of their moderation pipeline. Flagged items can be sent for additional checks or human review instead of being automatically published.
Image-Enabled AI Applications
Applications that combine user messages with image uploads can evaluate both types of content in one moderation workflow, subject to the model's input requirements. This can be useful for visual assistants, image discussion tools, and multimodal conversational interfaces.
AI Content Generation Products
Products that generate text can check model responses before presenting them to a user. A safety check can also be applied to user instructions before a generation request is sent. The result should be combined with the product's own rules and escalation process.
Internal Review and Risk Screening
Development teams can use the model to help prioritize content for review, identify potential policy violations, and build repeatable safety checks into testing pipelines. High-impact decisions should include appropriate human oversight.
Example: Understanding the Model's Output
The following examples illustrate the general output format. They are illustrative, not verified predictions from a live model call.
safeA safe result indicates that the submitted content was classified as safe under the model's taxonomy and instructions. It does not mean the content is factually correct, legally compliant, or suitable for every audience.
unsafe
S1
In this example, S1 represents a placeholder category code. The actual category must be interpreted using the taxonomy and prompt format for the exact model version being used. Do not treat the example code as a statement about a particular piece of content.
Integrating Llama-Guard-4-12B Through an API
Developers can integrate Llama Guard 4 into a backend service that accepts content, sends it for classification, and routes the result through the application's moderation logic. The precise request structure depends on the inference provider and endpoint.
A typical implementation involves these steps:
- Configure access to an endpoint that supports Llama-Guard-4-12B.
- Prepare the text and any supported image inputs in the required format.
- Submit the request using the provider's documented API schema.
- Parse the returned safe or unsafe classification and any category codes.
- Apply your own handling rules, logging, escalation, and review process.
Before implementing the integration, check the selected endpoint's authentication method, supported input modalities, response schema, model identifier, and operational limits. Not every endpoint exposes identical functionality.
If you are building a project around multiple AI models, explore the available options in the WhollyAPI models directory. Check the individual model listing to confirm availability and integration details.
Llama-Guard-4-12B Compared with a General-Purpose LLM
A general-purpose language model is designed to perform tasks such as answering questions, writing, summarizing, or reasoning. Llama Guard 4 has a narrower purpose: classify content according to safety guidelines.
| Area | Llama Guard 4 | General-purpose LLM |
|---|---|---|
| Primary role | Safety classification | Content generation and understanding |
| Typical output | Safe/unsafe and category codes | Natural-language answers or other generated content |
| Image support | Text with supported image inputs | Depends on the model |
| Best role in a system | Moderation and safety checks | The main application task |
These components can complement each other. A generative model handles the user's task, while Llama Guard evaluates content at selected points in the workflow. Neither component alone provides complete application security.
Limitations to Consider
Llama-Guard-4-12B can support a moderation strategy, but its classification should not be treated as infallible. Like other machine-learning classifiers, its judgments can be affected by ambiguous wording, context, adversarial inputs, and gaps in its training data.
- Not a complete security system: It does not replace authorization, access controls, abuse prevention, or application-level security.
- Context matters: A classification may not capture every nuance of a conversation or the intent behind a message.
- Image-input constraints: Image evaluation follows specific input requirements and is not a universal image-only moderation solution.
- Language coverage: Multilingual capability does not guarantee equal performance in every language. Validate the languages and content types used by your audience.
- False positives and false negatives: Some acceptable content may be flagged, while some harmful content may pass through.
- Specialized decisions: High-stakes areas may require current information, additional classifiers, domain-specific rules, or human review.
Test the model against representative examples from your application before deployment. Monitor classification quality over time and provide a clear path for handling uncertain or disputed cases.
Frequently Asked Questions
What is Llama-Guard-4-12B used for?
It is used to classify text and supported text-and-image inputs for safety. Developers can apply it to user prompts, AI-generated responses, and content moderation workflows.
Can Llama Guard 4 analyze images?
Yes. It supports multimodal safety classification for text combined with one or more images. It is not designed for image-only classification, and supported image input conditions should be followed.
What does the model return?
It returns a text classification indicating safe or unsafe content. Unsafe results can include codes identifying the applicable hazard categories.
Can it moderate both user prompts and AI responses?
Yes. It can be used to evaluate inputs before generation, outputs after generation, or both, depending on the application's architecture.
Does Llama Guard 4 guarantee that an AI application is safe?
No. It is one component of a broader safety strategy. Developers should combine classification with appropriate application rules, testing, monitoring, and human review where needed.
Is Llama Guard 4 a chatbot?
No. Its main purpose is safety classification rather than general conversation. It is typically integrated alongside a model that performs the main user-facing task.
Final Thoughts
Llama-Guard-4-12B gives developers a focused way to add safety classification to AI applications that handle text and images. Its ability to evaluate both incoming prompts and generated responses makes it a useful building block for moderation workflows.
The best results come from treating it as one layer in a carefully designed system. Validate its behavior with real examples, understand its supported inputs, and define what your application should do when content is flagged. With those measures in place, Llama Guard 4 can help make AI experiences more controlled and easier to manage.
Explore more AI models in the WhollyAPI model directory, or visit the WhollyAPI blog for more guides on building with AI APIs.
Similar articles you might like
The Second Chance for Low-Resolution Footage: Bria Video Upscaling
Learn how Bria Video Increase Resolution can improve low-resolution footage, when AI upscaling helps, and how to check results for artifacts and lost detail.
From Headshot to Host: Building Talking-Avatar Videos with P-Video Avatar
Learn how P-Video Avatar turns a single portrait into a talking video using a script or audio track, with practical tips for better lip-sync and results.